Fudan University · Hunyuan Team, Tencent · Tsinghua University

ExplorationBench

Can AI systems acquire unfamiliar rules through exploration? We test them in verifiable Alien Worlds, whose rules are executable and conflict with familiar knowledge.

0
alien worlds
0
discovery targets
0
held-out tasks
0
frontier systems
Leaderboard

Held-out accuracy under autonomous exploration.

Three independent trajectories per system and sandbox, ranked by Best@3, the highest M4. Every score is the mean of three answers per question.

held-out accuracy, percent

M0 and M4 come from the Best@3 trajectory; Mean@3 and Worst summarise all three. O@M0 and A4+O supply the complete rule set before exploration or after it. Each system runs at its highest reasoning setting. Aux counts the rules reported correctly in AlienCode and the rate of correct refusal on unprovable theorems in AlienLogic; it never enters M4.

Matched controls · one tool interface

Five exploration conditions.

From left to right the system takes a larger part in designing the experiments. The first two columns receive no environment feedback.

held-out accuracy at M4, percent

Autonomous is the Best@3 trajectory, and hindsight replays that trajectory's probes. Each control condition is one trajectory per system.

Figure 1 · how the gain builds

Held-out accuracy over four rounds.

Each curve is a system's Best@3 trajectory. Click systems to compare; the badge gives the retained gain M4 − M0.

The problem

Why exploration is hard to measure.

Evaluating exploration ability is difficult because two requirements are in tension.

Contamination

Known domains are already known

A correct answer may simply have been memorised, and contamination cannot be ruled out for a black-box model.

in tension
Verification

New claims cannot be graded

Checking a genuinely new result can take expert proof checking, costly experiments, or years. Without it, a real discovery and a confident mistake look identical.

The construction

New to the system, fully known to the evaluator.

Alien Worlds are executable, so every answer is checked exactly, and they conflict with familiar knowledge, so recall misleads rather than helps: SHATTER multiplies, EMIT(100) prints 127, and no primitive adds.

The sandboxes

AlienCode and AlienLogic.

Two deterministic, executable sandboxes. Every altered rule is covered by at least one held-out task, and no LLM acts as judge.

AlienCode

program synthesis · interpreter-graded

A small calculation language whose familiar-looking operators follow hidden semantics. Programs are graded by an interpreter on private inputs.

31
discovery targets
70
held-out tasks
5
private inputs / task

AlienLogic

formal proof · checker-verified

A first-order natural-deduction system with patched inference rules. A proof checker verifies every proof, and an unprovable theorem scores only when the system declines to prove it.

24
patched rules
70
held-out theorems
23
unprovable goals
Probing

Every rule has to be found by probing.

The manual is familiar; the world is not. Try a probe.

environment tool · deterministic · opaque feedback
The protocol

Explore with the world open. Answer with it closed.

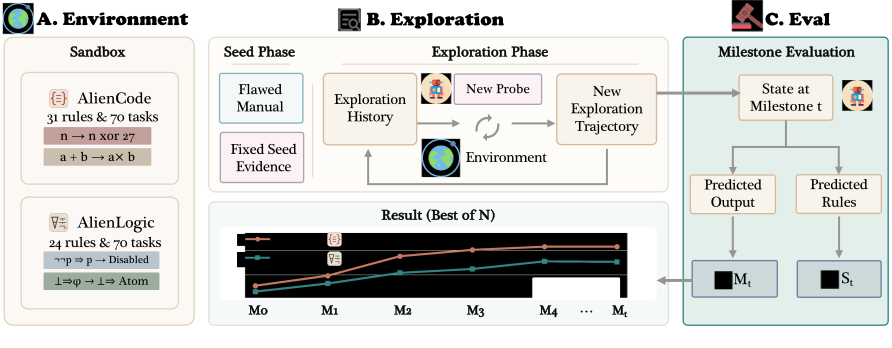
One continuous history, four rounds of probing, and no weight updates. After every round, a tool-disabled copy reports its rules and answers the held-out tasks.

ExplorationBench protocol overview: environment, exploration, evaluation
Six conditions · filled markers receive environment feedback
Eight findings

What ten frontier systems do in two alien worlds.

Whether exploration works, how discovering a rule relates to using it, and how reliably exploration succeeds.

RQ1 · Findings 1–3

Can AI systems acquire an alien world through exploration?

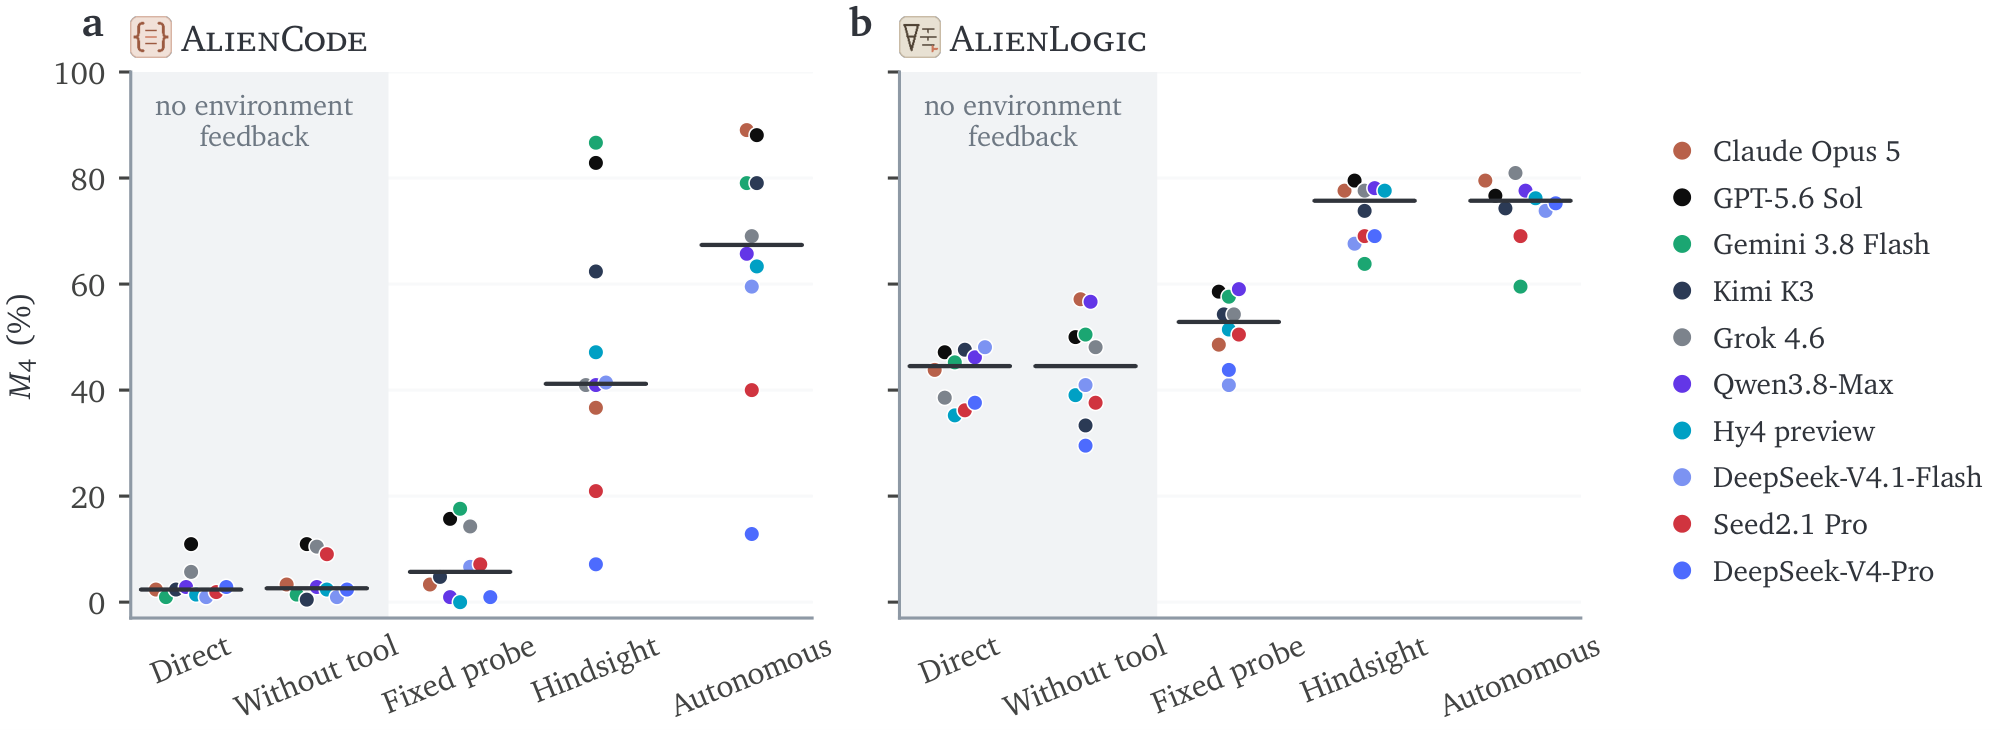
Four rounds lift AlienCode from at most 15.7% to 89.0%, while the same turns without feedback stay at or below 11.0%. Designing the probes matters more than receiving their results.

Held-out accuracy at M4 under direct, without-tool, fixed-probe, hindsight, and autonomous conditions in both sandboxes

Fig. 4 · Each dot is one system; the line marks the median. Shaded columns receive no environment feedback.

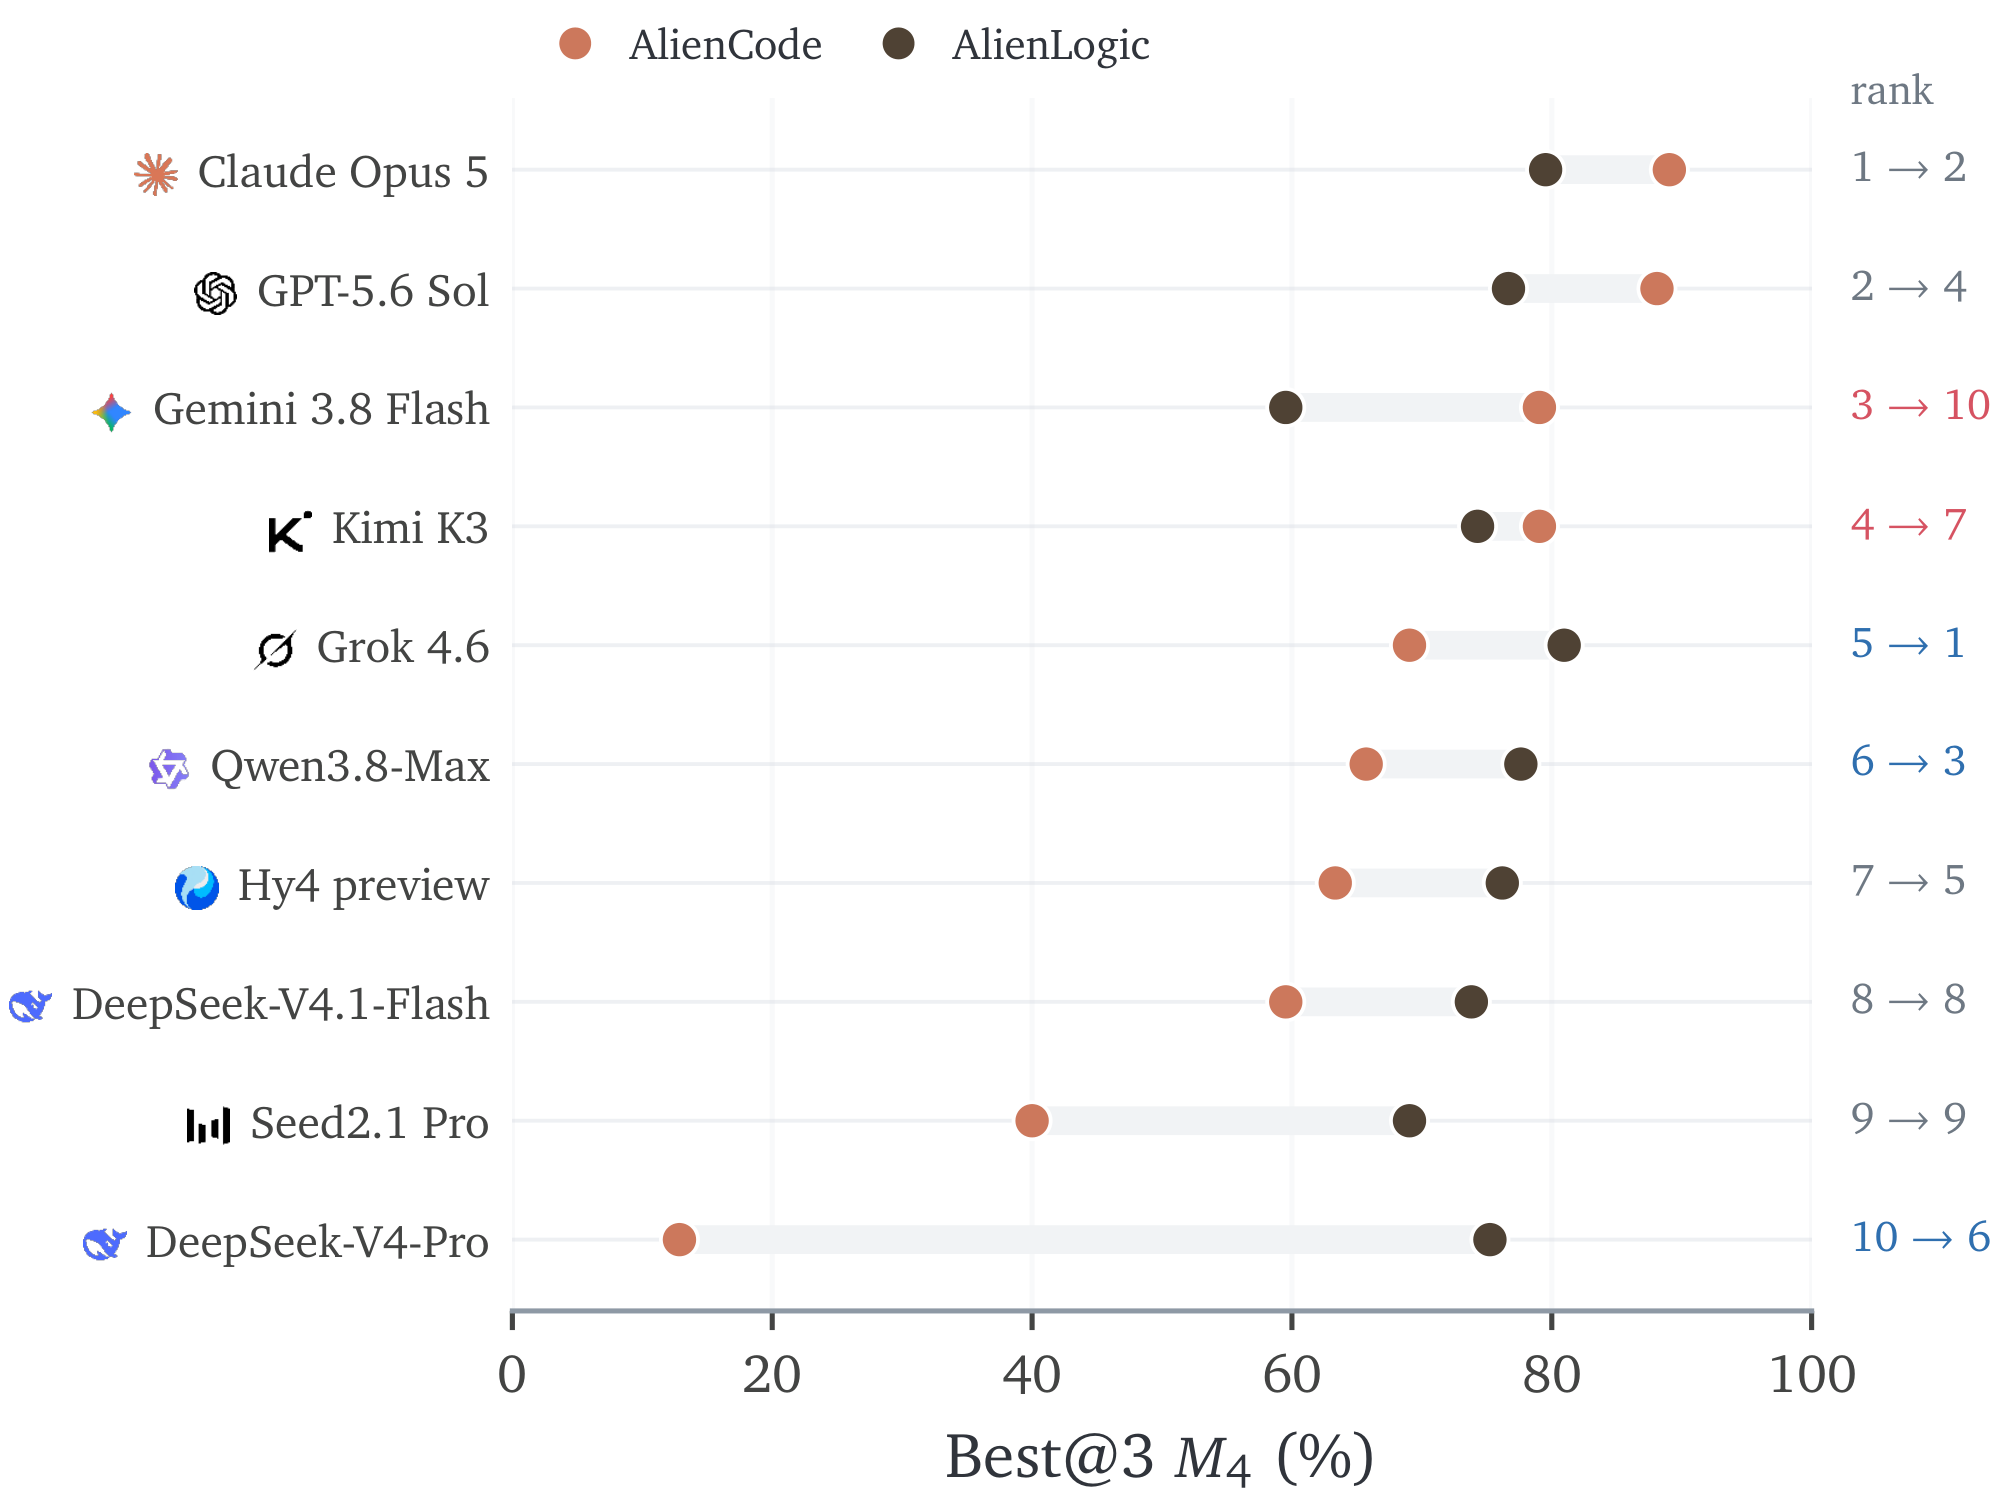
Each system's Best@3 M4 in AlienCode and AlienLogic, with its rank in each

Fig. 5 · A system's rank in one sandbox barely predicts its rank in the other (Spearman 0.35).

RQ2 · Findings 4–6

How does discovering a rule relate to using it?

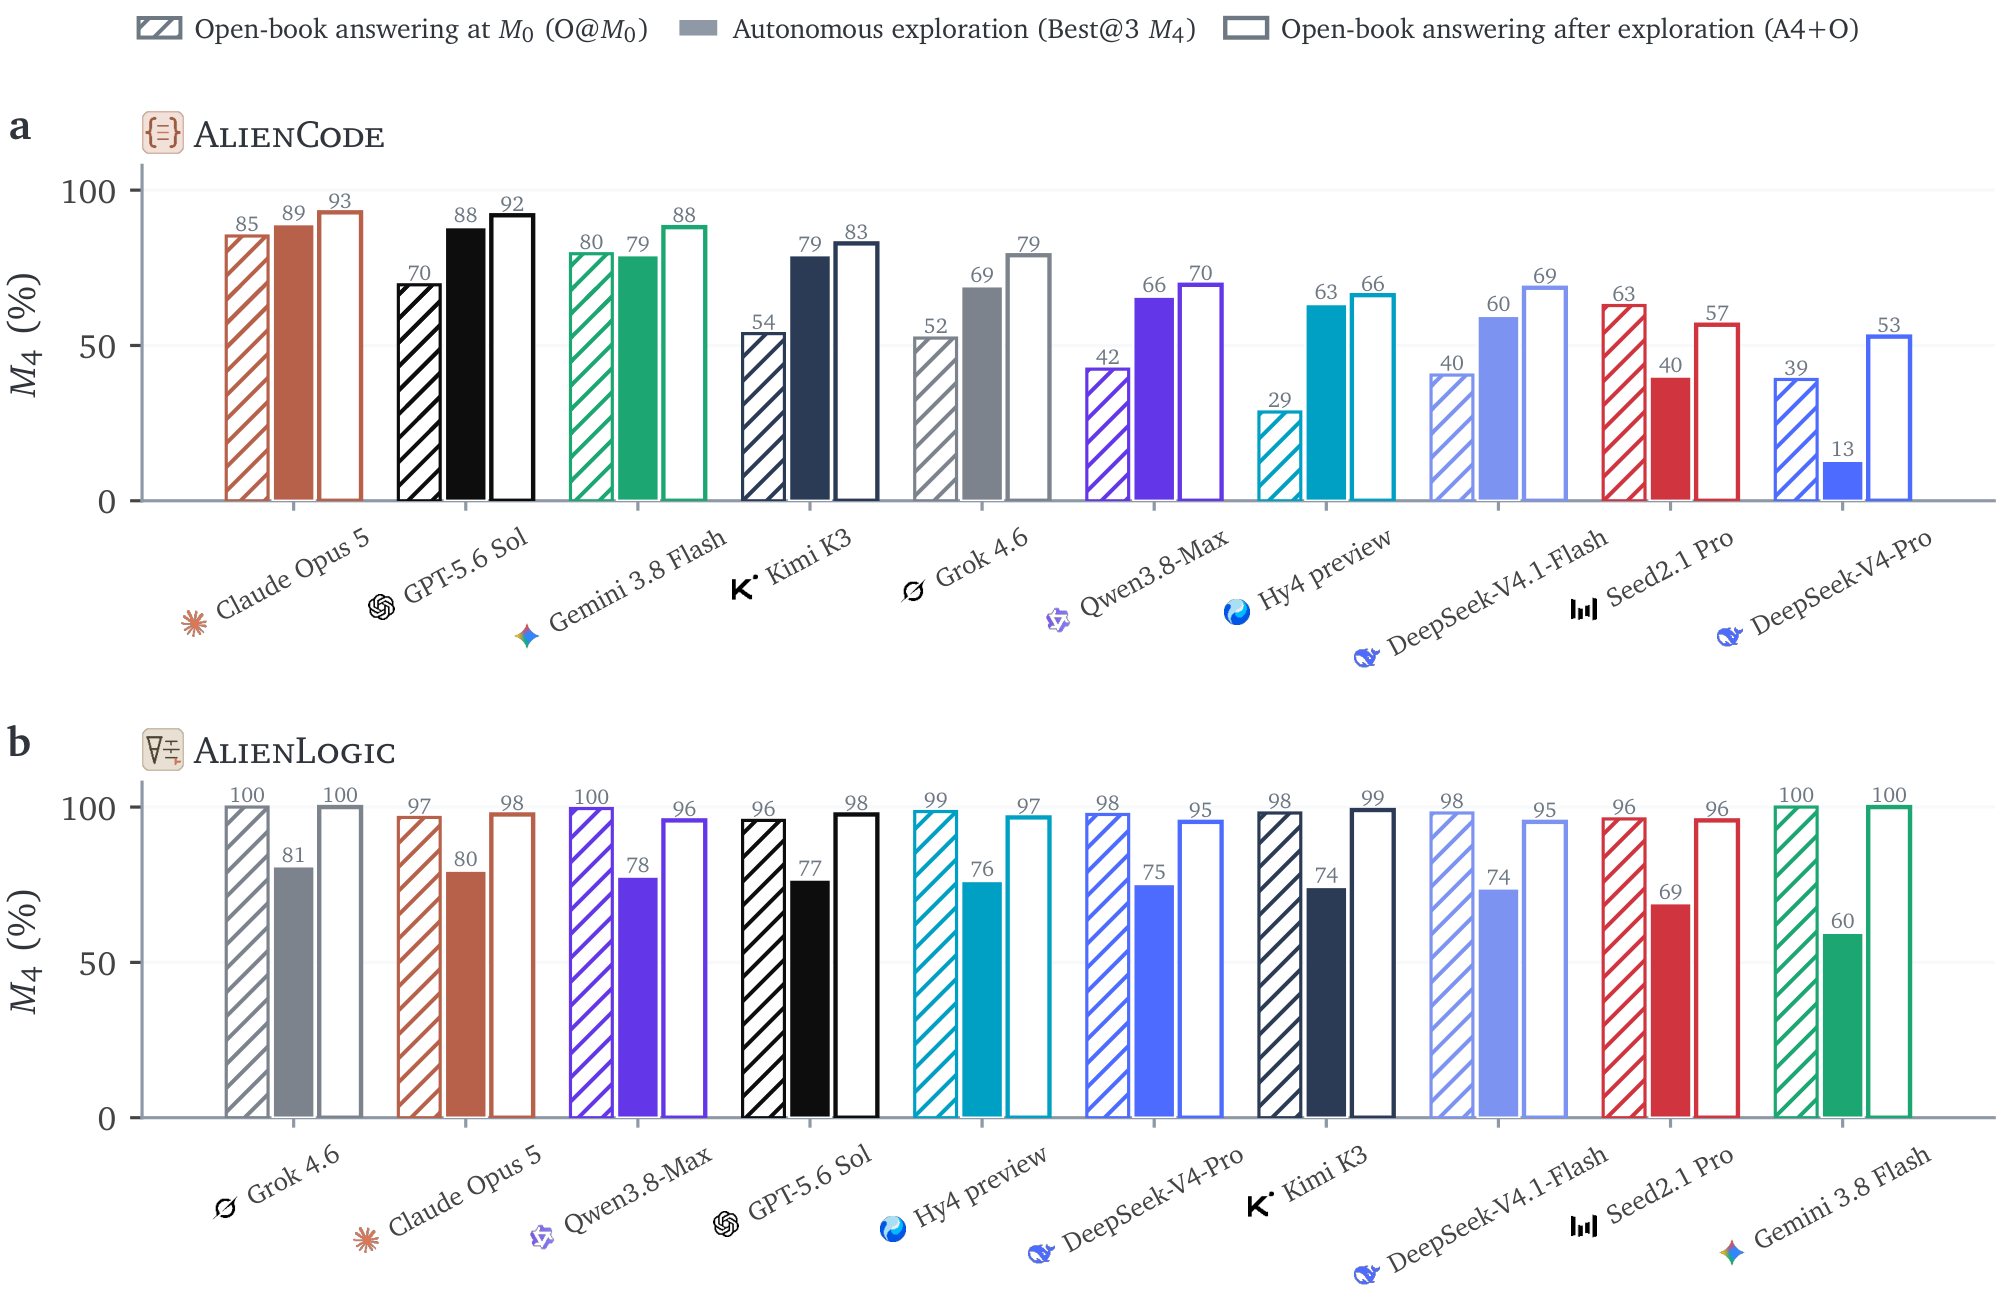
AlienLogic is limited by discovery and AlienCode by use. Two keystone rules decide most of AlienCode, and stating a rule still does not guarantee using it.

Held-out accuracy under open-book answering before exploration, autonomous exploration, and open-book answering after exploration

Fig. 6 · Open-book answering before exploration (hatched), autonomous exploration alone (solid), and open-book answering after it (outlined).

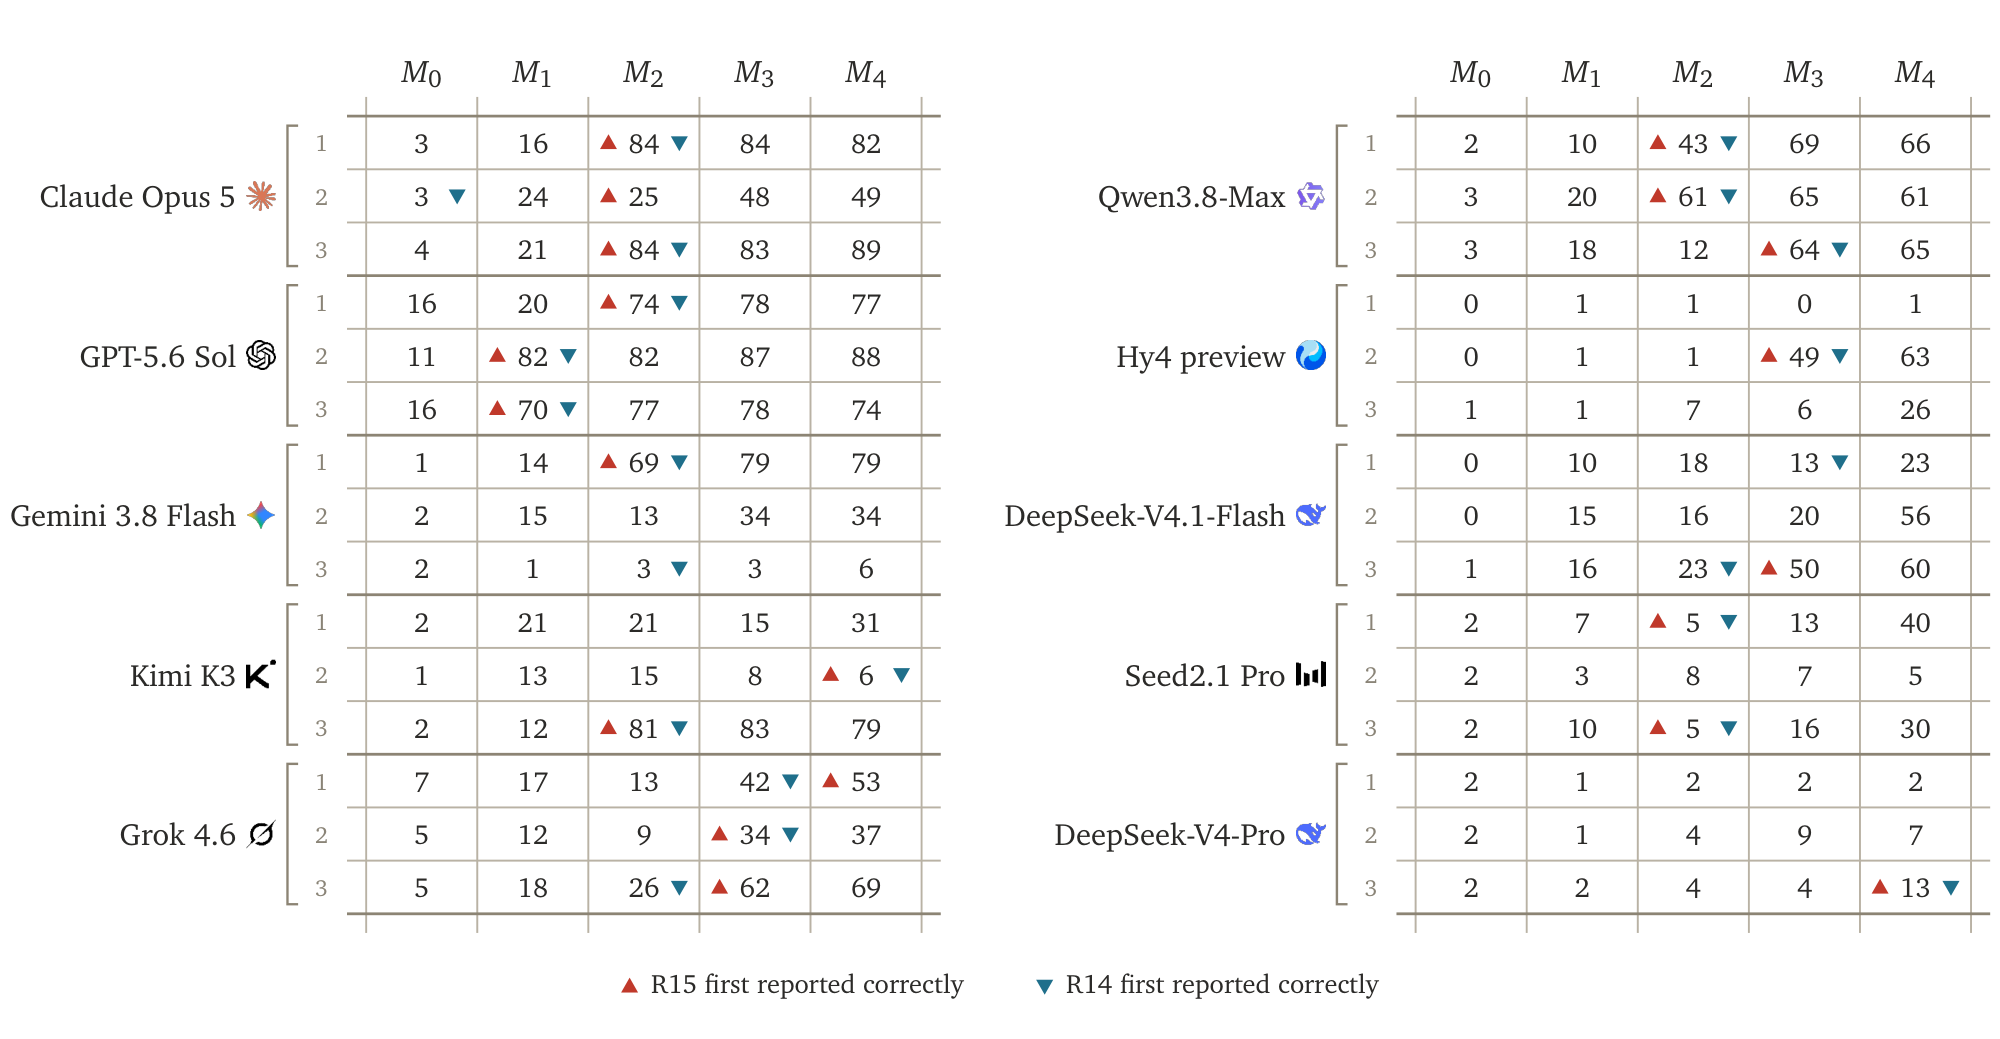
Held-out accuracy of every AlienCode trajectory by milestone, marking when R14 and R15 are first stated correctly

Fig. 7 · Triangles mark the milestone at which the rule report first states R15 (CARVE slice shift) and R14 (PLUCK index shift) correctly.

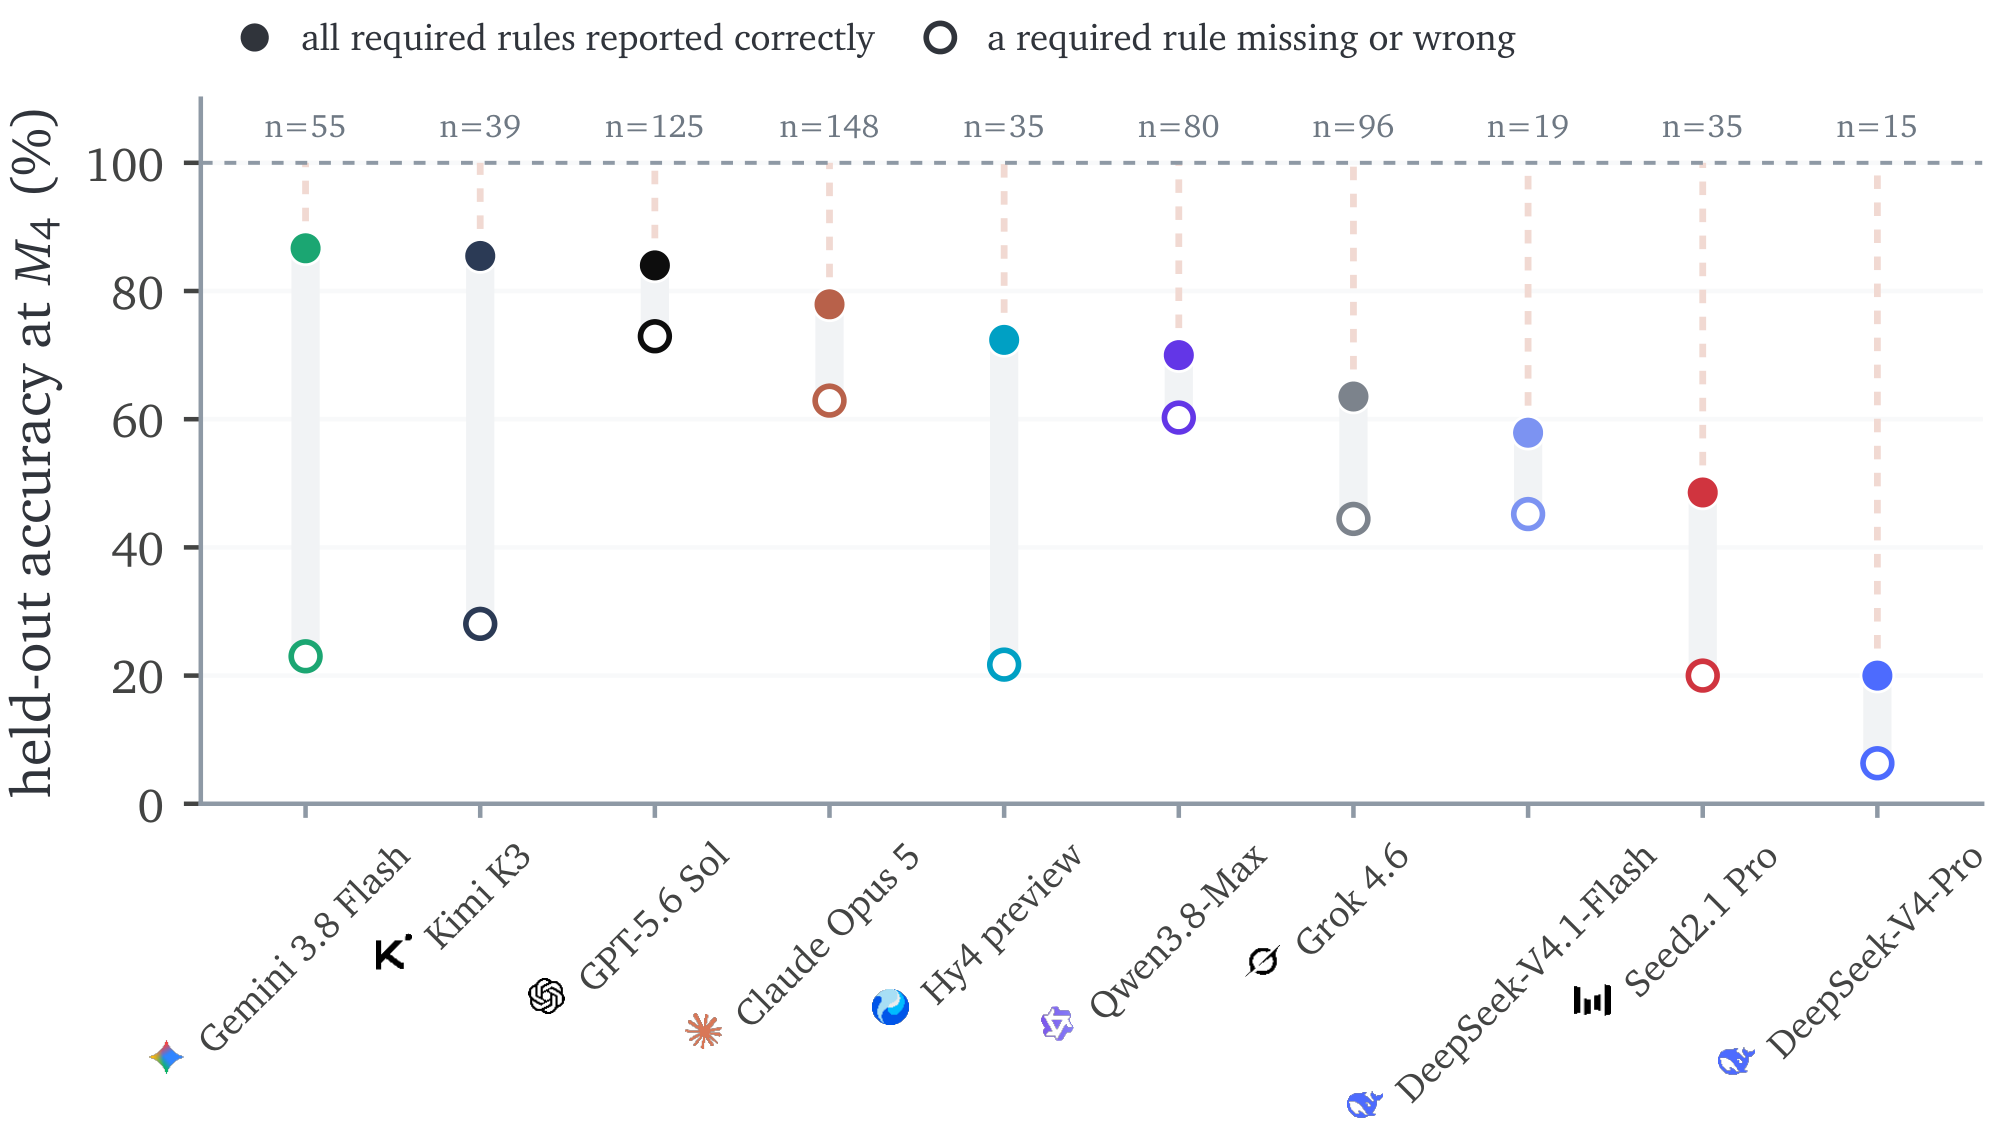
Accuracy on tasks whose required rules are stated correctly versus tasks with a rule missing or wrong

Fig. 8 · Tasks whose required rules the M4 report states correctly (filled) are still solved only 73.4% of the time.

RQ3 · Findings 7–8

How reliable is exploration?

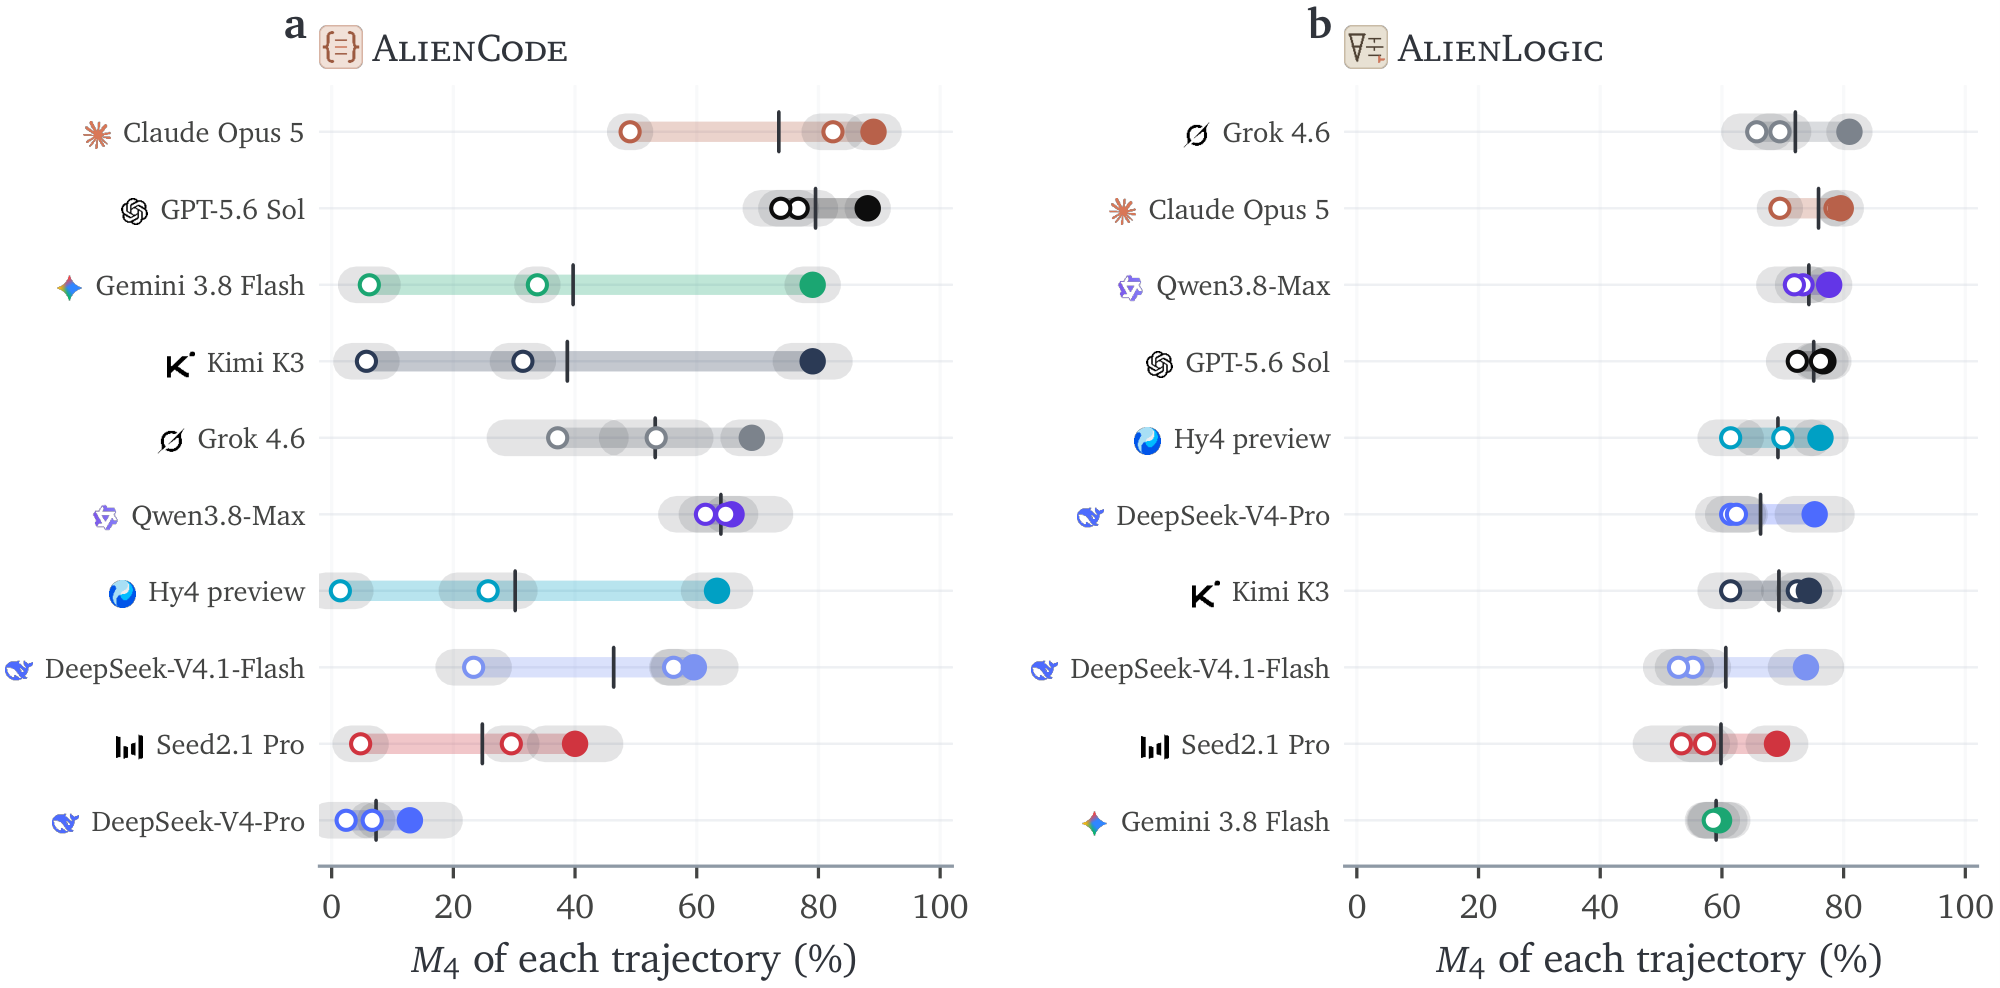
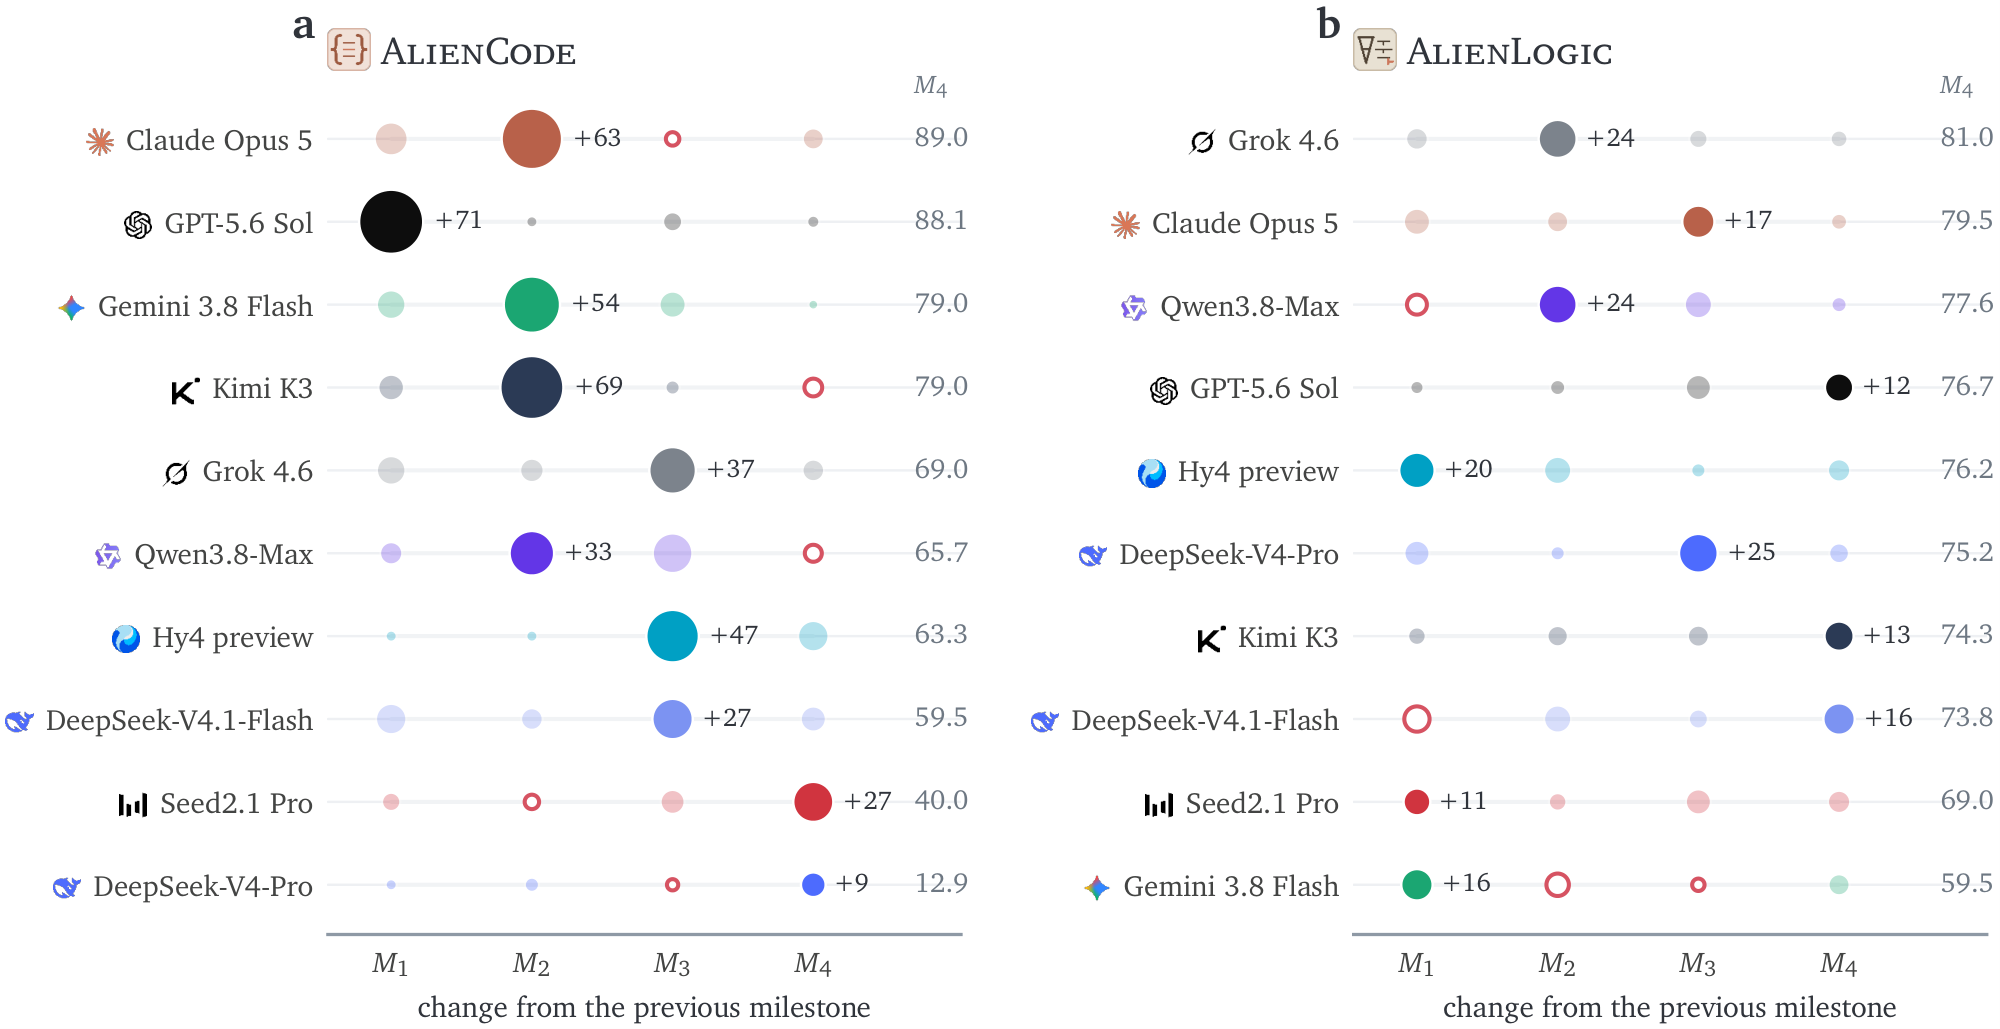
Repeated answers barely move, while one system's trajectories end tens of points apart. The largest gain arrives in a single round, and later rounds can undo it.

Each system's three trajectory endpoints with the answering noise of each

Fig. 9 · Dots are the three trajectories' M4; the grey halo is one standard deviation of that trajectory's three answers.

Per-round change in held-out accuracy along each system's Best@3 trajectory

Fig. 10 · Bubble area is the change from the previous milestone; the solid bubble marks the largest step, and a red ring marks a fall.

Paper

ExplorationBench: Measuring AI Systems' Exploration in Verifiable Alien Worlds

The same design can evaluate exploration wherever unfamiliar rules can be made executable and their consequences verified exactly.

Ming Zhang*†, Zhenghao Xiang*, Peizhong Gao*, Yujiong Shen, Yuhui Wang, Zhonghan Yue, Shihan Dou, Zhangyue Yin, Junjie Ye, Shichun Liu, Weihuang Zheng, Jiahao Chen, Jiayi Chen, Hongzhang Liu, Jiaqi Shao, Tao Gui†, Qi Zhang†, Xuanjing Huang, Suncong Zheng†, Maxm Pan†

Fudan University  ·  Hunyuan Team, Tencent  ·  Tsinghua University
*Equal contribution    †Corresponding authors

mingzhang23@m.fudan.edu.cn · tgui@fudan.edu.cn · qz@fudan.edu.cn
congzheng@tencent.com · maxmpan@tencent.com

@article{zhang2026explorationbench, title = {ExplorationBench: Measuring AI Systems' Exploration in Verifiable Alien Worlds}, author = {Zhang, Ming and Xiang, Zhenghao and Gao, Peizhong and Shen, Yujiong and Wang, Yuhui and Yue, Zhonghan and Dou, Shihan and Yin, Zhangyue and Ye, Junjie and Liu, Shichun and Zheng, Weihuang and Chen, Jiahao and Chen, Jiayi and Liu, Hongzhang and Shao, Jiaqi and Gui, Tao and Zhang, Qi and Huang, Xuanjing and Zheng, Suncong and Pan, Maxm}, journal = {arXiv preprint arXiv:2609.30199}, year = {2026} }

Evaluate your model on ExplorationBench

The tasks are not public. To have a model evaluated, contact us and we will run it under the same protocol as the leaderboard.